An LLM finetuning use case comparing Gemma and Llama2
Originally published on Medium.
Goal
This article guides you through setting up a local GPU machine for fine-tuning large language models (LLMs), Gemma and Llama2. It presents a case study comparing the two open models with valuable insights.
Why this article can help people interested in LLM?
- Be among the first to explore a detailed comparison of fine-tuning performance between Gemma and Llama2.
- Gain practical knowledge on the capabilities and limitations of fine-tuning both models.
Why this article can help developers?
- Accelerate your development journey by finding the setup and code for local GPU fine-tuning on Github
- Gain optimization insights through system metrics like loading time, runtime, and inference latency.
If you want to finish in 2 mins, you can only focus on italic sections: “Learning from the training operational observation” and “Learning from the question set responses”.
Context
It is exciting that Google just introduced the open models Gemma this Wednesday. Now, if we want to finetune an open model for our applications, we have two nice options, Llama2 and Gemma.
Moreover, the tools for fine-tuning are evolving rapidly. Huggingface, for instance, offers the TRL/SFTTrainer, which is compatible with both Gemma and Llama models. Comparing with the Llama2 finetuning example code I shared a few months ago, SFTTrainer stands out for its ease of use and its unified interface, simplifying the fine-tuning process for these open models.
Data
I utilized a Q & A dataset sourced from Kaggle Book Dataset. I have been using it for my previous LLM finetuning blog. The Q&A dataset consists of short dialogues focusing on authors and titles, and was automatically generated by Llama2)
Here are a couple of Q&A examples:
- {“id”: “406”, “data”: [“Who is the author of the book ‘Decipher’?”, “Stel Pavlou”]}
- {“id”: “690”, “data”: [“What is the title of the book written by Pergaud?”, “La Guerre Des Boutons”]}
Finetuning Setup
- Machines(single GPU):
- NVIDIA A10G 24G ; CUDA Version: 12.2
2. Base models:
- Gemma model: gemma-7b-it
- Llama2 model: llama-2–7b-chat
3. Installing libraries:
pip install -e .4. A few SFTTrainer Configuration(same for Gemma and Llama):
- batch_size: 4
- max_steps: 300
- packing: true
- PEFT method: LoRA
Finetuning Result
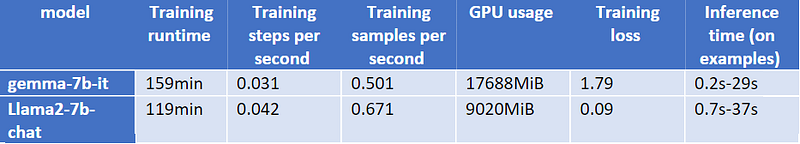
A. Training operation result: I have gathered a set of operational metrics. They are repeatable.
Learning from the training operational observation:
- Llama2 finetunes faster. This is likely because Llama2–7b is a smaller than gemma-7b.
- Llama2 shows better training loss on this finetuning task. Llama2 fits the finetuning data a lot better, but it may also subject to overfitting faster as training epochs increase)
- Llama2 outperforms in terms of loading and responding
- Llama2 responses a bit faster than Gemma. The response time highly depends on the number of generated tokens. The longer the response, the slower the inference. For my example questions tested on NVIDIA A10G 24G, inference time spans from 0.2s to 40s.
B. Inference quality result
— My evaluation question involves a set of 11 questions covering six distinct types of LLM tasks : (1) code generation. (2) mathematical calculation. (3) reasoning. (4) translation. (5) Q&A on common knowledge. (6) Q&A on finetuning data. Here is the question set:
a. [Type 1]Write a python function to select the smallest number from two integers. Please respond concisely.
b. [Type 2]What is the result of 2+8*3-(4+4)? Please answer concisely.
c. [Type 3]Peter’s salary is $1000 per week. Alice is $1200 per week. If they work for three weeks, how much does Alice earn more than Peter?
d. [Type 4]Please translate ‘我在使用大语言模型做产品开发’ in English
e. [Type 5]Please write a 100 word introduction about President Obama for me to learn about him
f. [Type 5]What are the top 5 biggest countries by area. Please answer concisely.
g. [Type 5]How many countries are in Europe by 2023.
h. [Type 6]Who is the author of the book ‘The Book of Lights’? Please answer honestly and concisel
i. [Type 6]Who is the author of the book ‘Liberty Falling’? Please answer honestly and concisely,
j. [Type 6]Who is the title of the book written by an llm practicioner? Please answer honestly and concisely
k. [Type 6]Who is the author of the book ‘tibetan food handbook’? Please answer honestly and concisely
— The evaluation is iteratively conducted with variations in these key dimensions: ((1) Alternating between the Llama2 and Gemma models, (2) Comparing the base model with its fine-tuned counterpart, and (3) Modifying the quantization bit.
The complete set of responses can be found in the provided spreadsheet. Each tab corresponds to a unique execution using the identical set of evaluation queries. The names of the tabs reflect the three dimensions mentioned earlier. Any instances of hallucination in the responses are distinctly marked in red.
Learning from the question set responses
- Gemma base model exhibits superior performance in tasks related to mathematical calculations and reasoning. This is mainly because the Llama2 open model wasn’t specifically designed to prioritize these types of tasks.
e.g.; for question b, Llama2-base-8bit replies 2+8*3-(4+4)=28; gemma-base-8bit returns the correct answer
- Under low quantization settings, such as 4-bit, the response quality of both Gemma and Llama2 is poor. The responses show more hallucination and focus less on prompt’s requirement. Gemma appears to perform slightly better than Llama2 in maintaining response quality.
e.g.: for question d, Llama2-base-4bit cannot translate well
- Gemma and Llama2 exhibit inconsistent responses to questions about common knowledge, likely a consequence of the differences in the training data employed for the original models.
e.g.: for question g, Llama2 has the right answer while Gemma not
- Following the fine-tuning process, both Llama2 and Gemma are able to answer questions related to the fine-tuning data knowledge as anticipated, though their responses are not always correct.
e.g.: question k is made-up for finetuning validation. Both finetuned Gemma and finetuned Llama2 can respond well
- Fine-tuning can negatively impact other Large Language Model (LLM) tasks, a trend that is clearly observed in both Llama2 and Gemma.
e.g.: Gemma base model can answer 2+8*3-(4+4) correctly but gemma finetuned model cannot.
- Increasing finetuning epochs may enhance performance in the targeted fine-tuning task, but it can adversely affect performance in other Large Language Model (LLM) tasks.
e.g.: comparing to llama2–ft-8bit model, llama2-ft-8bit-more-epochs model completed 50% more epochs. The “more epoch” model responds closer to the finetuning data style, but cannot even translate question d well.
Summary
This article explored a fine-tuning use case with the open-source models Gemma-7b-it and Llama-7b-chat. It demonstrated the implementation of finetuning code on a local GPU. The article also offered insights and comparisons between Gemma and Llama2, along with the author’s perspective.
In the end, I want to express my gratitude to both Meta and Google for their commitment to open-source LLMs. Developing Generative AI (GenAI) technologies is a complex endeavor, and sharing their findings with the developer community fosters collaboration and progress.
While these models have limitations, it’s crucial to remember that supporting and providing feedback is more productive than mere criticism. I believe that both companies will continue to refine their open models and tools, ultimately benefitting the GenAI community and the wider world.
If you have any questions or need any help on your use case, welcome to discuss with the author.